Available in MyClaw

GPT 6 Astra

OpenAI's most intelligent and aligned model — state of the art on computer use, browsing, software engineering, cybersecurity, science, and professional work. Available to run in MyClaw.

Pricing

GPT 6 Astra API Pricing

OpenAI publishes list prices for gpt-6-astra. Use the rates below to plan high-reasoning agent workloads in MyClaw. Hosting and model tokens bill separately.

Standard Input
$10 / 1M tokens
Cached Input
$1 / 1M tokens
Cache Writes
$12.50 / 1M tokens
Standard Output
$50 / 1M tokens

Long-context surcharge after 272K input tokens

OpenAI bills the full request at 2× input and cache rates and 1.5× output when the prompt's input tokens exceed 272K.

Long-context input
$20 / 1M
Long-context cached input
$2 / 1M
Long-context cache writes
$25 / 1M
Long-context output
$75 / 1M

Batch and Flex are 50% of the applicable Standard rates. Fast mode is 2× the applicable rates. Fine-tuning is not supported. Tool calls such as search and computer use can add per-call fees. Knowledge cutoff: April 30, 2026. Free tier is not listed on OpenAI's rate-limit table.

Capabilities

What OpenAI Positions GPT 6 Astra For

Official OpenAI API docs describe Astra as the escalate ID for the hardest end-to-end jobs, not a rename of GPT 5.6 Sol and not Google DeepMind's Project Astra.

Hardest End-to-End Reasoning

OpenAI positions GPT 6 Astra for complex multi-step work that has to stay coherent from the first request to a finished result, using the context and tools you provide.

Coding and Computer Use

The official model page lists coding and computer use among Astra's primary jobs. Treat that as a job-shape signal, then judge a swap against your own repository and tools.

Research and Document Creation

OpenAI also lists research and document creation. Astra accepts text and image input and returns text. Audio and video are not supported, so do not plan a voice agent on this ID.

Responses API Tools

OpenAI documents support for web search, file search, image generation, code interpreter, hosted shell, apply patch, skills, computer use, MCP, and tool search on the Responses API.

Streaming and Structured Output

Streaming, function calling, and structured outputs are supported. Fine-tuning is not. Reasoning effort values are low, medium, high, xhigh, and max.

Not Project Astra

Do not confuse OpenAI's gpt-6-astra with Google DeepMind's Project Astra. Different company, different product, different API.

Official demo

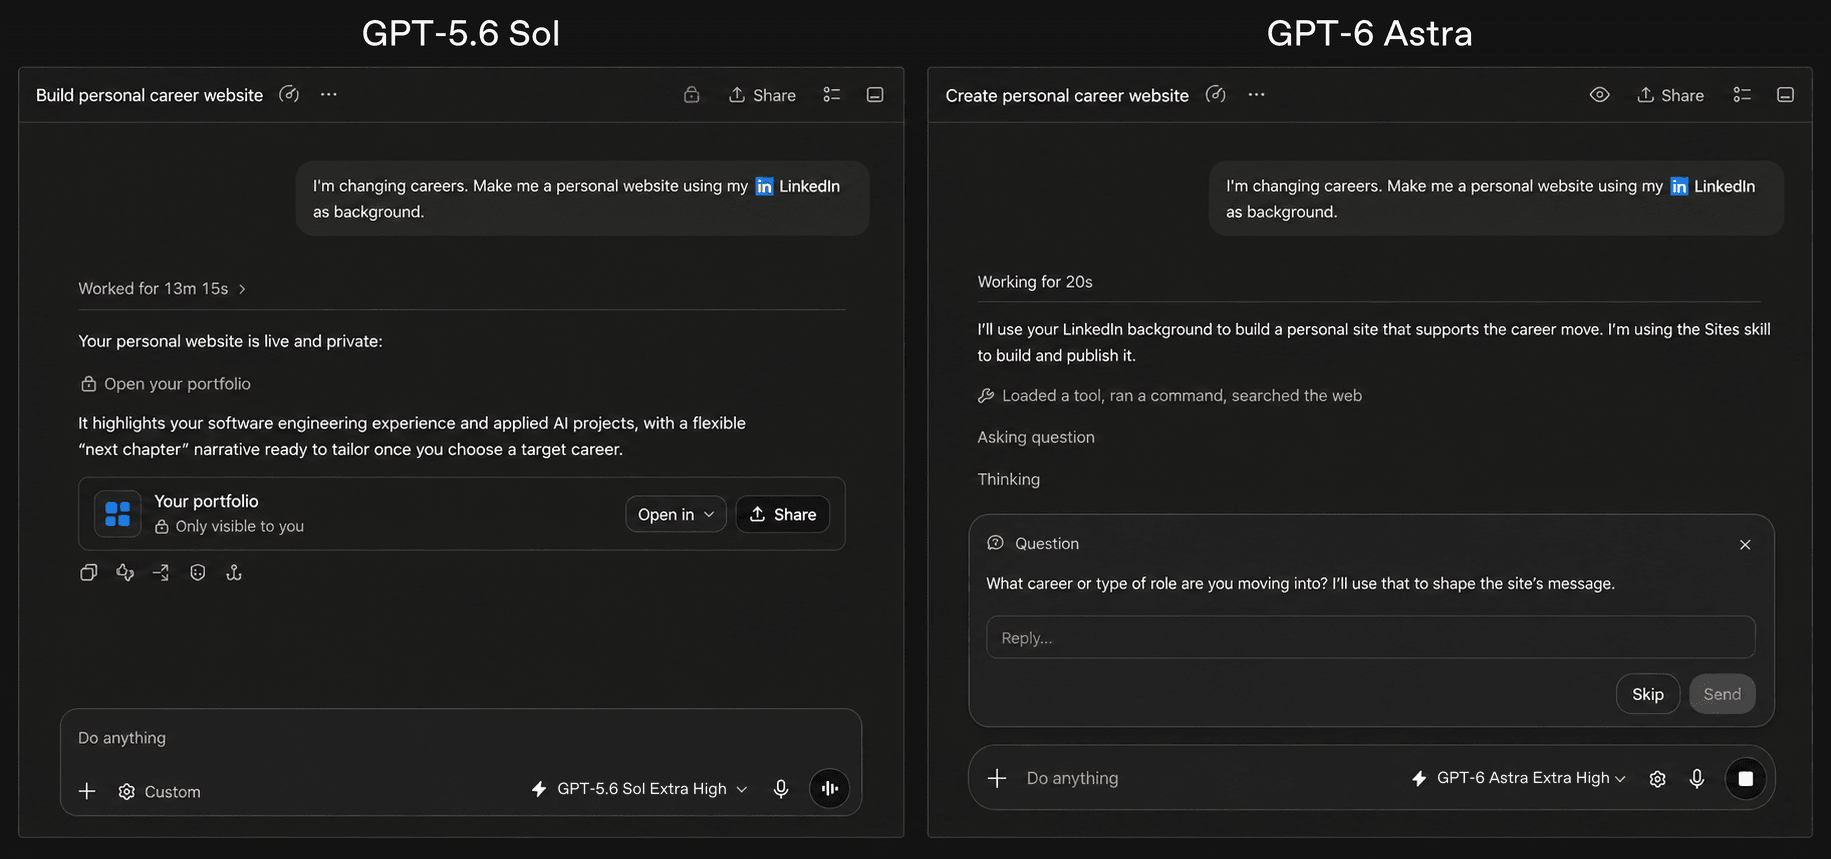
Computer-use demo vs GPT-5.6 Sol

OpenAI shows Astra completing demanding computer-use work faster than GPT-5.6 Sol. On OSWorld 2.0 latency simulations: 72.6% at ~40 minutes vs Sol 65.7% at ~75 minutes.

Side-by-side OpenAI demo: Astra asks clarifying questions and finishes faster on the same career-website task.

OpenAI demo of GPT-6 Astra helping build a career website versus GPT-5.6 Sol

Agents Last Exam

Best computer-use accuracy at lower API cost

Astra reaches 59.3% accuracy, compared with 53.6% for GPT-5.6 Sol and a reported 55.5% for Claude Opus 5. At peak settings, Astra uses approximately 65% fewer output tokens than Opus 5.

Agents’ Last Exam

GPT-6 AstraGPT-5.6 SolClaude Fable 5Claude Opus 5 · reported score only

Accuracy

API cost per task (USD)

Opus 5 is shown as a reported-score reference; no API-cost point is provided. View OpenAI source

BenchCAD

Professional CAD workflows with better cost curves

BenchCAD python tool: Astra 95.9 percent vs Sol 83.3 percent and Fable 5.1 84.3 percent on OpenAI chart.

BenchCAD (python tool)

GPT-6 AstraGPT-5.6 SolClaude Fable 5.1

Mean voxel IoU

API cost per task (USD)

Claude scores use the evaluation modifications described in the Fable 5.1 system card. View OpenAI source

Terminal-Bench Science

Science workflows that stay in the terminal

Terminal-Bench Science 0.1: Astra 64.6 percent vs Fable 5.1 52.6 percent and Sol 22.4 percent.

Terminal-Bench Science 0.1

GPT-6 AstraGPT-5.6 SolClaude Fable 5.1Claude Fable 5Claude Opus 5

Resolution rate

API cost per task (USD)

Each point represents a tested configuration; API costs are estimates. View OpenAI source

ARC-AGI-3

Abstract reasoning near saturation

ARC-AGI-3: Astra 99.9 percent vs Sol 7.8 percent on OpenAI table; Responses API harness footnote applies.

Score

GPT-6 AstraClaude Opus 5GPT-5.6 Sol

Astra was evaluated with OpenAI’s Responses API harness. View OpenAI source

Alignment

Lower misaligned computer-use outcomes

Computer-use safety stress test lower-is-better: Astra 2.4 percent misaligned outcome rate on OpenAI chart.

Misaligned outcomes · lower is better

GPT-6 AstraClaude Fable 5.1Claude Opus 5Claude Fable 5GPT-5.6 Sol

Research evaluation without the additional protections normally deployed in Codex and ChatGPT Work. View OpenAI source

Official evaluations

OpenAI GPT-6 Astra benchmark tables

Full vendor-reported comparison set from the OpenAI announcement. Dashes mean no published figure for that model on this row.

View complete benchmark tables
Computer use
BenchmarkGPT-6 AstraGPT-5.6 SolClaude Fable 5.1Claude Opus 5
Agents' Last Exam59.3%53.6%—55.5%
OSWorld 2.0 (offline, partial)72.6%65.7%—70.2%
ScreenSpot-Pro (no tools)92.7%76.9%——
Professional
BenchmarkGPT-6 AstraGPT-5.6 SolClaude Fable 5.1Claude Opus 5
AutomationBench41.4%18.1%31.4%26.9%
BenchCAD95.9%83.3%84.3%82.1%
BrowseComp91.5%90.4%—90.8%
Internal Data Science Tasks40.9%30.5%——
Coding
BenchmarkGPT-6 AstraGPT-5.6 SolClaude Fable 5.1Claude Opus 5Gemini 3.8 Flash
Terminal-Bench 4.057.9%37.3%55.8%52.6%19.1%
DeepSWE v1.174.1%72.7%67.4%73.7%73.8%
FrontierCode 1.1 Extended64.5%60.6%63.6%63.6%56.3%
FrontierCode 1.1 Main53.3%47.5%50.9%53.4%43.6%
Academic and science
BenchmarkGPT-6 AstraGPT-5.6 SolClaude Fable 5.1Notes
Terminal-Bench Science 0.164.6%22.4%52.6%OpenAI official pair
FrontierMath Tier 4 (v2)97.6%83.0%87.8%Headline also ~98%
GPQA Diamond96.0%94.6%93.7%Near ceiling
GeneBench Pro37.1%32.3%—Science and health
HealthBench Professional63.4%60.5%58.1%Science and health
Long context and abstract reasoning
BenchmarkGPT-6 AstraGPT-5.6 SolNotes
MRCR v2 8-needle 256K-512K100%91.5%Long context
MRCR v2 8-needle 512K-1M96.3%73.8%Long context
ARC-AGI-399.9%7.8%Responses API harness
ARC-AGI-295.0%92.5%Abstract reasoning
ARC-AGI-198.5%97.5%Abstract reasoning
Alignment (lower is better unless noted)
BenchmarkGPT-6 AstraGPT-5.6 SolNotes
Computer-use safety stress test2.4%22.0%Lower is better
Same + AutoReview1.8%4.3%Lower is better
Internal circumvention0.00%0.29%Lower is better
Internal hallucination4.2%12.2%Lower is better

Source: https://openai.com/index/gpt-6-astra/ (Sep 2026). OSWorld is offline/partial. ARC-AGI-3 uses OpenAI Responses API harness.

Availability

Rolling out across ChatGPT, API, Azure, and Bedrock

OpenAI is rolling Astra out in phases: limited organizations first, then ChatGPT Plus/Pro/Business/Enterprise, plus the OpenAI API, Microsoft Azure, and AWS Bedrock. MyClaw already routes gpt-6-astra for hosted agents.

API ID gpt-6-astra

Use Responses / Chat Completions with model id gpt-6-astra. Zero Data Retention is supported for eligible API customers.

Enterprise off by default

OpenAI says Enterprise access starts off until an admin enables it. Pro/Business/Enterprise also get GPT-6 Astra Pro.

Preparedness gating

Standard access refuses advanced dual-use security work. Trusted Access / Daybreak expands defensive workflows under OpenAI preparedness controls.

Preparedness

First Critical cybersecurity designation

Astra is OpenAI's first model to reach the Critical cybersecurity capability level under the Preparedness Framework. OpenAI reports stronger jailbreak robustness and alignment than GPT-5.6 Sol, while advanced cyber access stays gated.

Critical cyber threshold

With the right tools and access, OpenAI says Astra can find previously unknown flaws and develop exploits across well-protected systems without step-by-step human guidance. Standard product access refuses advanced exploit work.

Stronger alignment vs Sol

OpenAI's safety overview says Astra is better aligned than GPT-5.6 Sol, with fewer high-severity misalignment flags across 54,000+ internal Codex tasks, and safer behavior in browsing and workplace computer settings.

Monitorability tradeoff

OpenAI also reports decreased CoT monitorability versus Sol in adversarial settings. Read the safety overview and system card before routing sensitive agent workloads.

Model Family

GPT 6 Astra vs. GPT 5.6 Sol

Astra is the escalate ID for the hardest OpenAI agent, computer-use, and coding jobs. Keep Sol when the ticket already closes or finished-job math still favors $5 / $30.

FeatureGPT 6 AstraGPT 5.6 Sol
Official RoleMost capable OpenAI model for hardest end-to-end workFlagship GPT 5.6 tier for high-reasoning agent work
API IDgpt-6-astragpt-5-6-sol
MyClaw AvailabilityAvailable to run in hosted MyClaw agentsAvailable to run in hosted MyClaw agents
Context / Max Output1,050,000 / 128,000 tokensNot publicly listed on the Sol announcement page
Standard Price (per 1M)$10 input / $50 output$5 input / $30 output on the MyClaw card
Reasoning Effortlow, medium, high, xhigh, maxIncludes a published max effort and ultra subagent mode
ModalitiesText + image in; text out; no audio or videoUsed in MyClaw for text-first agent workflows
When to ChooseChoose Astra for demanding computer-use, coding, and multi-step tasks that benefit from deeper reasoning.Keep Sol for jobs that already pass or when finished-job math still favors $5 / $30

Sol pricing above is the MyClaw card rate. Astra prices are OpenAI Standard list rates checked against official API docs in September 2026. This page does not invent independent benchmark scores.

MyClaw Agent Fit

Where GPT 6 Astra Fits in MyClaw

Astra is most useful when a hosted agent can combine deep reasoning and computer use with persistent files, terminal tools, browsers, and scheduled execution.

Escalate the Jobs Sol Leaves Open

Freeze one ticket Sol already struggled with. Rerun it on GPT 6 Astra at the same reasoning effort, then let tests and diffs score whether the harder ID closes the job.

Computer-Use and Coding Loops

Astra is the OpenAI escalate for multi-step coding and computer use. A hosted MyClaw agent gives that work files, tools, and an always-on workspace.

Choose the Model That Fits the Task

Keep GPT 5.6 Sol for jobs it already closes. Route the hardest agent, computer-use, and long-horizon coding loops to GPT 6 Astra when finished-job math favors the escalate.

Pin Reasoning Effort Before You Compare

Official effort values are low, medium, high, xhigh, and max. A max Astra pass next to a cheaper Sol setting is a settings gap, not a model gap.

Watch the 272K Line

Prompts over 272K input tokens bill the full request at long-context rates. Know whether your agent prompt stays under that line before you compare stickers.

Switch Models in the Same Workspace

Leave logs, diffs, and artifacts in the hosted workspace so the next run starts from the work, not a blank chat. Hosting and model tokens bill separately.

Similar Models

Explore Related Agent Models

Compare GPT 6 Astra with other strong coding, reasoning, and agent-ready models you can evaluate in MyClaw.

GPT 6 Astra FAQ

GPT 6 Astra on MyClaw

Put GPT 6 Astra to work

Bring your next coding, research, or computer-use task to a hosted workspace with persistent files and tools.